Mid Semester 2024 — the paper, worked through.
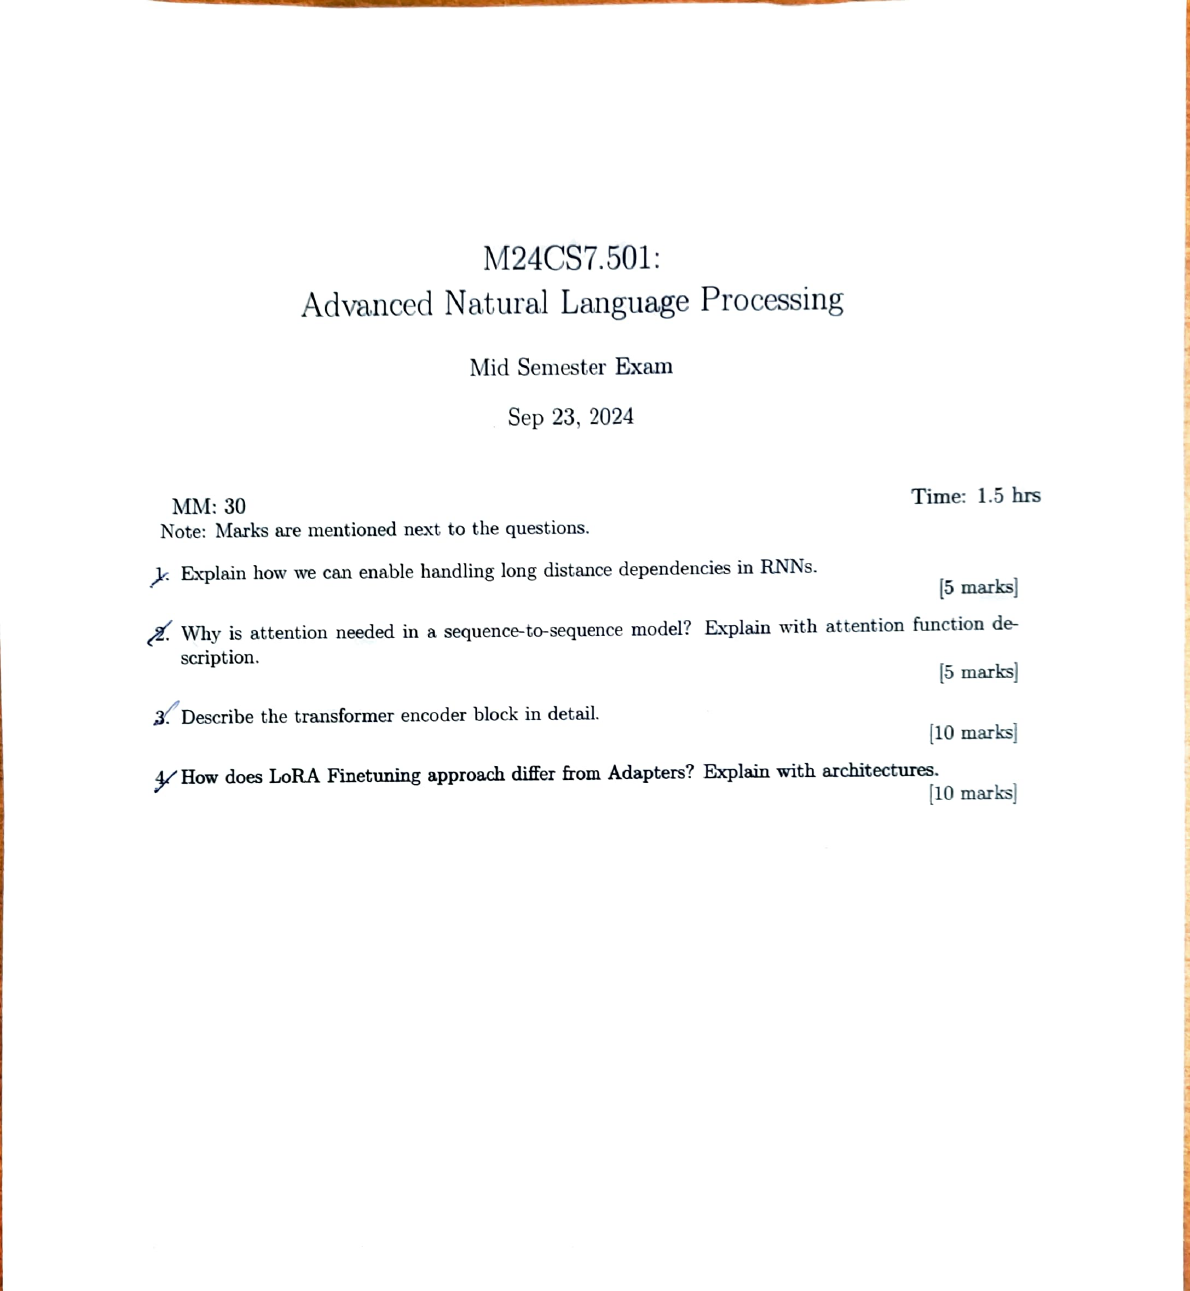
This is the 2024 mid-semester paper for M24CS7.501: four questions, 30 marks, and 90 minutes. It moves from classical sequence models to transformer encoders and parameter-efficient fine-tuning. There is no official key for this paper, so the worked answers show a clear, well-structured way to respond.
§1The paper
The two five-mark questions cover RNNs and seq2seq attention. The two ten-mark questions cover the transformer encoder and efficient fine-tuning. Use the marks to decide how much detail each answer needs.
Before you start
Same shape as 2023: every question is an open-ended "explain / describe / compare" prompt with no numerical work. But the balance has shifted. In 2023 the whole paper was pre-transformer; here, two thirds of the marks (20 out of 30) are on transformer-era material: the encoder block itself, and PEFT methods that only make sense once you have a large pretrained transformer to fine-tune. The 2024 syllabus has caught up with the field.
- The two 5-mark questions want tight answers, so think five distinct correct claims per question, one for each mark. Overwriting them steals time from Q3 and Q4.
- The two 10-mark questions want structured answers: a diagram, the defining equations, a walk through each sub-component, and a "why does it look this way" paragraph. A wall of prose without equations will not clear a 10-marker.
Q4 asks for architectures, plural. Answering only "LoRA is low-rank, Adapters are bottlenecks" without sketching where each of them lives in the transformer block loses half the mark. The word "architectures" in the question is not decoration.
§2Q1 · Long-distance dependencies in RNNs
The question, verbatim
1. Explain how we can enable handling long distance dependencies in RNNs. [5 marks]
How to approach it
Only five marks, so keep it tight. Start with the failure mode a vanilla RNN has — the vanishing / exploding gradient in back-propagation through time — because "enable handling" only makes sense once you have named what stops it. Then give the fix: gating, in the LSTM's cell-state form and the GRU's update-gate form, both of which turn the multiplicative gradient path into a nearly additive one. Close with the more radical answer — attention removes recurrence altogether. Five marks, five distinct claims.
Worked answer
Where the problem comes from
A vanilla RNN reads a sequence one token at a time and updates a hidden state through a shared recurrence:
In principle, this recurrence can carry information from step 1 to step 100 — the hidden state at any late position is a function of every earlier one. But training with back-propagation through time unrolls the network into a -layer deep computation, and the gradient of the loss with respect to an early hidden state is a product of Jacobians, one per time step. That product either vanishes (spectral norm < 1, geometric decay to zero) or explodes (spectral norm > 1, geometric blow-up). Long-range gradients never reach the early weights — so a vanilla RNN has the capacity for long dependencies but not the trainability.
Fix 1 — gating (LSTM, GRU)
Both LSTM and GRU replace the single update with a small circuit of sigmoid gates that decide, per component, how much of the past to keep and how much of the new candidate to write. On any dimension where the "keep" gate is near 1, the state passes through unchanged and the gradient across that step is close to the identity — the multiplicative gradient path becomes an additive one.
LSTM. Keeps a separate cell state that is updated by an additive rule, gated by a forget gate and an input gate :
This is the famous constant error carousel: when the forget gate is near 1, gradients flow along the cell-state highway across many time steps essentially unchanged. Long dependencies stop being killed by BPTT.
GRU. Fuses the cell and hidden state into one vector and uses only two gates — an update gate and a reset gate . The update gate interpolates between the old state and the new candidate:
When is near 0, the past is preserved verbatim and the gradient across that step is again close to the identity. Fewer parameters than LSTM, same additive-highway trick.
Gates turn the recurrence's multiplicative gradient path into a nearly additive one on any step the gate says "keep". That is the single reason gated RNNs learn long dependencies where vanilla RNNs cannot.
Fix 2 — get rid of recurrence entirely (attention / self-attention)
The other answer is more radical: if recurrence is the reason long-range signal is fragile, remove it. Self-attention lets any position look directly at any other position with a single matrix multiply — the distance-1 shortcut a plain RNN never had. Every token has an path length to every other token, so long-range dependencies stop being a training problem at all. This is the escape hatch the transformer takes, and it is what makes the rest of this paper (Q3, Q4) possible.
Notice the two answers point in opposite directions. Gates keep the recurrence and patch its gradient path. Attention throws out the recurrence and gives every position a direct edge to every other. Both work — but only the second scales, which is why the field moved on.
§3Q2 · Why attention in seq2seq
The question, verbatim
2. Why is attention needed in a sequence-to-sequence model? Explain with attention function description. [5 marks]
How to approach it
The question is two halves. First, why: name the bottleneck in vanilla seq2seq and argue that different target words need different source content, so the decoder needs a fresh source view at each step. Second, the function: write the three-line attention block — score, softmax, weighted sum — and name at least one concrete score function (additive Bahdanau or multiplicative Luong). Five marks, so keep it to one crisp diagram-in-words plus the equations.
Worked answer
Why attention is needed
A vanilla encoder-decoder for machine translation (Sutskever et al. 2014) reads the whole source sentence with an RNN and summarises it into a single fixed-length vector — the final encoder hidden state — which is then handed to the decoder as its only source-side input. The decoder must generate the entire target sentence from that one vector.
Two problems fall out of this design:
- The bottleneck. A fixed-size vector cannot carry all of a long source sentence. Empirically, translation quality drops sharply once the source exceeds roughly 20–30 tokens, because the encoder is being asked to compress unbounded content into a bounded state.
- Different targets need different source content. Consider translating "the red car is fast" into French — "la voiture rouge est rapide". When the decoder is producing voiture, it needs to look at car. When it is producing rouge, it needs to look at red. One fixed vector cannot serve both — it averages them or forgets one. What the decoder actually needs is a different source view at every target step.
Attention (Bahdanau et al. 2015) fixes both. The encoder keeps all its per-position hidden states . At each decoder step, a soft alignment is computed over those states and a fresh context vector is produced — a weighted sum of encoder states, weighted by how well each source position matches the current decoder state. The decoder can "look back" at any source token at any time.
The attention function
At decoder step , attention runs three lines:
The score function is the model's judgement of how relevant source position is to producing the next target token. Two standard choices:
Additive (Bahdanau, 2015) — a tiny one-hidden-layer feedforward network on the concatenated decoder and encoder states:
Multiplicative / dot (Luong, 2015) — a bilinear form, cheaper because it is essentially a matrix multiply:
Once is computed, the decoder produces the next word from a combination of its own state and the context vector: .
Attention is not just an accuracy fix for long sentences. It is the realisation that "which piece of input do I need right now?" is itself something the model can learn. Once you can learn a soft lookup over encoder states, you no longer need a recurrence to carry information across positions — you can just attend. That observation is what leads to the transformer.
§4Q3 · Transformer encoder block, in detail
The question, verbatim
3. Describe the transformer encoder block in detail. [10 marks]
How to approach it
A ten-mark structural question. Walk from input to output, naming each sub-component and giving its defining equation. The full checklist: input embedding + positional encoding, multi-head self-attention (with the scaled dot-product formula and how heads are computed and combined), residual connection and LayerNorm, position-wise feedforward network, residual and LayerNorm again. Close with the complexity and one line on why the block looks this way. Aim for one equation-plus-paragraph per sub-component — that is roughly two marks each, which lines up with the ten.
Worked answer
Setup — the block's input and output
An encoder block takes a matrix — one row per input token, embedded into a shared -dimensional space. It returns a tensor of the same shape, so blocks stack cleanly. A transformer encoder is such blocks in series (the original paper uses ).
Before the first block, two things happen once to the input:
- Each token id is turned into a -dimensional token embedding via a learned lookup table.
- A positional encoding — a fixed sinusoidal signal or a learned vector — is added to each embedding. Self-attention is otherwise position-agnostic; without this, the model would treat the sentence as a bag of tokens.
Sub-layer 1 — multi-head self-attention
The first sub-layer lets each token look at every other token in the sequence. For a single head, three learned projections turn the input into queries, keys, and values:
where and . Scaled dot-product attention is then:
Reading it row by row: for each query token, dot it with every key to get a raw score, divide by so the softmax does not saturate at high dimension, softmax over the sequence to get attention weights, and take a weighted sum of the value vectors. Each output row is a soft lookup — a mixture of value vectors, weighted by query-key similarity.
Multi-head. Instead of one large attention with dimension , the block runs heads in parallel with per-head dimension . Each head has its own . Their outputs are concatenated and projected back:
Different heads learn to attend to different kinds of structure — one may track syntactic dependencies, another may track co-reference. Splitting into heads is essentially free (the total parameter count is roughly the same as a single-head attention of dimension ) but is strictly more expressive.
Dot products of two random -dim vectors have variance proportional to . Without the denominator, softmax inputs grow with , saturating the softmax and killing gradients. Dividing by keeps the scale roughly unit variance regardless of dimension.
Residual connection and LayerNorm (round 1)
The attention output is added back to its input via a residual connection, and the sum is normalised:
The residual gives gradients a direct path around the sub-layer, letting deep stacks train stably. LayerNorm normalises each token vector to zero mean and unit variance across its features, then rescales with learned per-feature and . Unlike BatchNorm, it depends only on the token itself, so it works with variable sequence lengths and small batches.
Sub-layer 2 — position-wise feedforward network
The second sub-layer is a small MLP applied independently to each position. Two linear layers with a non-linearity in between:
with and — the inner dimension is typically . The original paper uses ReLU; modern implementations (BERT, GPT-2 onwards) use GELU. The point is that self-attention only mixes information across positions linearly; the FFN adds a per-token non-linear transformation, and does most of the block's per-position compute.
Residual and LayerNorm (round 2)
Same pattern as after attention:
is the output of one encoder block, ready to be fed into the next.
The block, at a glance
| Step | What it does | Shape |
|---|---|---|
| Input | token embedding + positional encoding | |
| Multi-head self-attention | each token attends to every token; heads run in parallel | |
| Add & Norm | residual, then LayerNorm across features | |
| Position-wise FFN | two-layer MLP, applied independently at each position | |
| Add & Norm | residual, then LayerNorm again |
Complexity
Self-attention forms an attention matrix, so the block is in time and in memory. Quadratic in the sequence length. This is the cost the field has spent the last five years trying to reduce — Flash Attention, sparse attention, linear attention, state-space models. But inside one encoder block, this cost is what buys you an path length between any two tokens, which is the whole point.
Read the block as two sub-layers with the same shape — each is (mix, then residual + norm). Self-attention mixes information across tokens; the FFN mixes information across feature dimensions. Every subsequent architecture in this course either changes how the across-tokens mixer works (Mamba, Flash Attention, sparse variants) or how the across-features mixer scales (Mixture-of-Experts). The template is the same.
§5Q4 · LoRA vs Adapters
The question, verbatim
4. How does LoRA Finetuning approach differ from Adapters? Explain with architectures. [10 marks]
How to approach it
Frame both as parameter-efficient fine-tuning (PEFT) — same problem (fine-tune a large pretrained model cheaply by touching only a small number of new parameters, keeping the original weights frozen), two different architectural answers. Sketch each one: where it plugs into the transformer block, what its forward equation looks like, how many parameters it adds. Then give the differences on axes that actually matter: serial vs parallel placement, inference latency, mergeability, expressiveness. The word "architectures" in the question is a rubric signal — you need diagrams-in-words or pictures, not just prose.
Worked answer
The shared problem
Full fine-tuning of a modern pretrained transformer means updating all of its billions of parameters and storing a full-sized checkpoint per downstream task. That is expensive to train and impossible to serve if you have many tasks. Parameter-efficient fine-tuning methods freeze the original weights and add a small number of new, trainable parameters — typically 0.1%–5% of the base model — that specialise it to the task. Two of the most widely used are Adapters (Houlsby et al. 2019) and LoRA (Hu et al. 2021).
Adapters — architecture
An adapter is a small bottleneck MLP inserted inside the transformer block, in series with the frozen sub-layers. Given an input , the adapter does:
Three pieces: a down-projection that squashes to a small bottleneck of size , a non-linearity (GELU / ReLU), and an up-projection back to the model dimension. A residual connection carries the input around it, and is initialised to zero so the adapter starts as an identity — the model behaves exactly like the frozen base at initialisation and only drifts as the adapter learns.
The adapter is inserted twice per transformer block: once after the multi-head self-attention sub-layer, once after the FFN sub-layer. The block becomes:
x
 ├─> MultiHead-SelfAttn (frozen)
 ├─> Add + LayerNorm
 ├─> Adapter  (trainable, ~few % params)
 ├─> FFN (frozen)
 ├─> Add + LayerNorm
 ├─> Adapter  (trainable)
 └─> out
Only , , and the LayerNorm parameters are trained. Everything else is frozen. Adapters typically add ~1–5% of the base model's parameter count per task.
LoRA — architecture
LoRA does not insert anything into the block. It adds a trainable low-rank update in parallel to selected frozen weight matrices — typically the query and value projections inside self-attention. If is one of the frozen projections, LoRA replaces it with:
with and , . The factor is a scaling constant. is initialised at random and is initialised to zero, so at the start of training and the model is exactly the frozen base — the same "start as identity" trick as adapters.
Forward pass through a LoRA-augmented projection:
Two matrix multiplies down the low-rank path, in parallel with the frozen . Trained parameters per LoRA-adapted matrix: . With rank or 16 applied to just and , LoRA typically trains <1% of the base model's parameters.
x ──> W (frozen)     ──┐
      │                 ├─> add ─> h
      └─> A ─> B (train)┘
The critical differences
| Axis | Adapters | LoRA |
|---|---|---|
| Where it sits | Inside the block, after each sub-layer | Parallel to chosen weight matrices (usually , ) |
| Placement in the graph | Serial — the forward pass goes through it | Parallel — added to the frozen matmul |
| Inference latency | Adds latency at every layer, both training and inference | Zero extra latency at inference — the update can be merged into : |
| Trained shape | Bottleneck MLP with a non-linearity | Linear low-rank factorisation, no non-linearity |
| Trainable params | ~1–5% of the base | Often <1% of the base (tunable via ) |
| Task switching | Swap adapter weights in place | Swap by unmerging one and merging another (or serve unmerged) |
Because and have the same shape, they can be summed once, after training, into a single . Inference then runs exactly the same matmul the original model did — one matrix multiply, no extra layers. Adapters cannot do this because the non-linearity between the down- and up-projections is not a linear operation, so there is nothing to fold back into the frozen weights.
Why each design exists
Adapters came first and are the more general recipe — the bottleneck can learn any non-linear transformation, and the same trick generalises to inserting small modules anywhere in the graph. Their weakness is that they add serial depth: every adapter is one more layer of forward computation the request has to pass through, and stacking them across all 24 or 32 transformer blocks measurably slows inference.
LoRA takes a specific bet: the update that fine-tuning would learn is approximately low-rank, so it can be represented as with very small . In exchange for that assumption, LoRA gets three practical wins — fewer trained parameters, no inference latency (thanks to mergeability), and effortless multi-task serving (keep , keep a stack of small pairs on disk, load the pair for the task you want).
The single sentence that captures the difference: adapters make the network deeper, LoRA makes selected weight matrices richer. Because "deeper" costs inference latency and "richer via a low-rank update" does not, LoRA has become the default parameter-efficient method for large models — every serving stack from Hugging Face PEFT to vLLM has first-class LoRA support, and multi-tenant LoRA serving is a real production pattern.